 /
White paper
/
White paper
White paper
I built an essay that can rewrite itself to stay evergreen. Here's how it works.
Section 1 · Introduction
Most written content is published once and then left alone to go stale. A client update, a country guide, a market outlook or a running news story is accurate on the day it is issued, and it dates as the subject moves on. Keeping it current and evergreen is manual work. Someone has to reread the piece against what has happened since and revise the lines that are no longer true or out-of-date.
This paper proposes a solution, called the live and breathing essay. It is live because the document stays wired to the dataset it was written from, so it keeps getting tested against new evidence. It is breathing because that test happens on a rhythm.
An implementation of this architecture runs on the Global AI Regulation Tracker, under a tab called Enforcement Trends. The page reads as an ordinary essay. But behind the scenes it is rendered from a JSON file, a machine readable text format, and every statement in the essay is stored in it as its own record. Once a week a scheduled job checks the tracker dataset for new entries and proposes revisions to the statements those entries affect, for me to accept or reject.
The idea is to treat an essay like an application, built from five components. The frontend essay is served to the reader, and the backend mesh holds every statement in it. The algorithm works out what has changed and rewrites only the part affected. The scheduler runs it on a clock, and the approval mechanism lets a person accept or reject each change before it is published.
The frontend is an ordinary web page, but with two twists:
The 'mesh' is basically the data skeleton that sits behind the essay. Every statement lives in it as its own data object, and each one carries the metadata a machine needs to work with it. That metadata is an identifier of its own, the source it rests on, the date it was last tested against that source, and the subject it answers for. Think of it as a graph.
JSON is the most viable format of this graph. See below example.
{
  "statements": [
    { "key": "enf-014",
      "source": "gpdp-2026-04",
      "date": "2026-04-02",
      "subject": { "topic": "enforcement",
                   "jurisdiction": "IT" },
      "text": "Regulators act under existing privacy law."
    },
    { "key": "gpm-021",
      "source": "oj-l-2024-1689",
      "date": "2025-08-01",
      "subject": { "topic": "general purpose models",
                   "jurisdiction": "EU" },
      "text": "Model providers carry transparency obligations."
    }
  ],

  "sources": {
    "gpdp-2026-04": {
      "title": "Provvedimento 2 April 2026",
      "url": "https://example.org/gpdp/2026/04" },
    "oj-l-2024-1689": {
      "title": "Regulation (EU) 2024/1689",
      "url": "https://example.org/eu/2024/1689" }
  },

  "manifest": [
    { "id": "gpdp",
      "url": "https://example.org/gpdp/feed.xml",
      "added": "2026-01-11" },
    { "id": "oj-l",
      "url": "https://example.org/eu/oj/feed.xml",
      "added": "2026-01-11" }
  ],

  "ledger": ["9f2a41c8d6e0b537",
             "1c7d90ab34f6e2d1",
             "4e88b0195ac7f6d2"],

  "routing": {
    "enforcement / IT":            "enf-014",
    "enforcement / EU":            "enf-014",
    "general purpose models / EU": "gpm-021"
  },

  "residual": [
    { "hash": "6b18e5f2a90c4d73",
      "date": "2026-06-19",
      "subject": "insurance / SG",
      "note": "Mattered, and no statement owns it." }
  ]
}
statements The prose a reader is served, one object
per statement, each carrying its key, its source, its date and its subject.sources The evidence the statements bind to, held once
and referred to by identifier, so several statements can rest on the same
instrument.manifest A declared list of everything the system is
allowed to read. Anything not on the list is never read, so adding a source is an
explicit change with a record.ledger A record of everything already taken in, stored
as a content hash of each item rather than a position in a feed. A content hash is a
short fingerprint computed from the item's own text, so the same item always hashes the
same and a changed item hashes differently. Positions break silently when a feed
reorders, while hashes make a rerun return exactly what the first run did, and what
counts as new is whatever is not already in this list.routing Which statement answers for which subject.
This is the map the algorithm resolves against. Write it by hand while the document is
small, or derive it from what each statement already cites once it is not. It has to be
rebuilt whenever statements are added or removed. When a statement moves to a new home,
its future updates follow it there, so rebuilding the map sends incoming data to the
right place.residual A holding area for relevant updates that
match no existing heading, signalling when a new heading needs to be written. Several
items piling up on one subject means the document has no heading covering it.
Listing 1. An example mesh, cut down to two statements. The fields above
sources are rendered to the page and the structures below it are not.
The algorithm should:
This component is configuration rather than code. A cron expression, a workflow schedule or a hosted trigger will run the algorithm on a clock.
A minimum viable approval mechanism performs four functions.
The approval mechanism can come in various forms, including:
A change is written to the mesh only after a person accepts it. The frontend rebuilds only then, carrying the date of that decision.
This component is optional. Connect the algorithm's output directly to the mesh and the document updates itself, which is fine for generic content where a wrong statement costs little. Include the approval mechanism where a person has to be accountable for what the document says. The running implementation includes it because the essay states what the law requires.
Here is how the five components work together in practice.
Everything above describes the architecture. This section walks through how it is implemented on Google Cloud to power the Enforcement Trends essay on the Global AI Regulation Tracker. The frontend essay is served by Firebase Hosting, the mesh is one object in Cloud Storage, the algorithm is a Cloud Run service, the scheduler is a Cloud Scheduler job, and the approval mechanism is an admin dashboard I built and host separately from the site.
Enforcement Trends is an essay about how AI regulation is actually enforced around the world. It covers which areas or issues regulators scrutinise most heavily, and whether enforcement actions differ across markets.
The date on the page is the date the essay last changed.
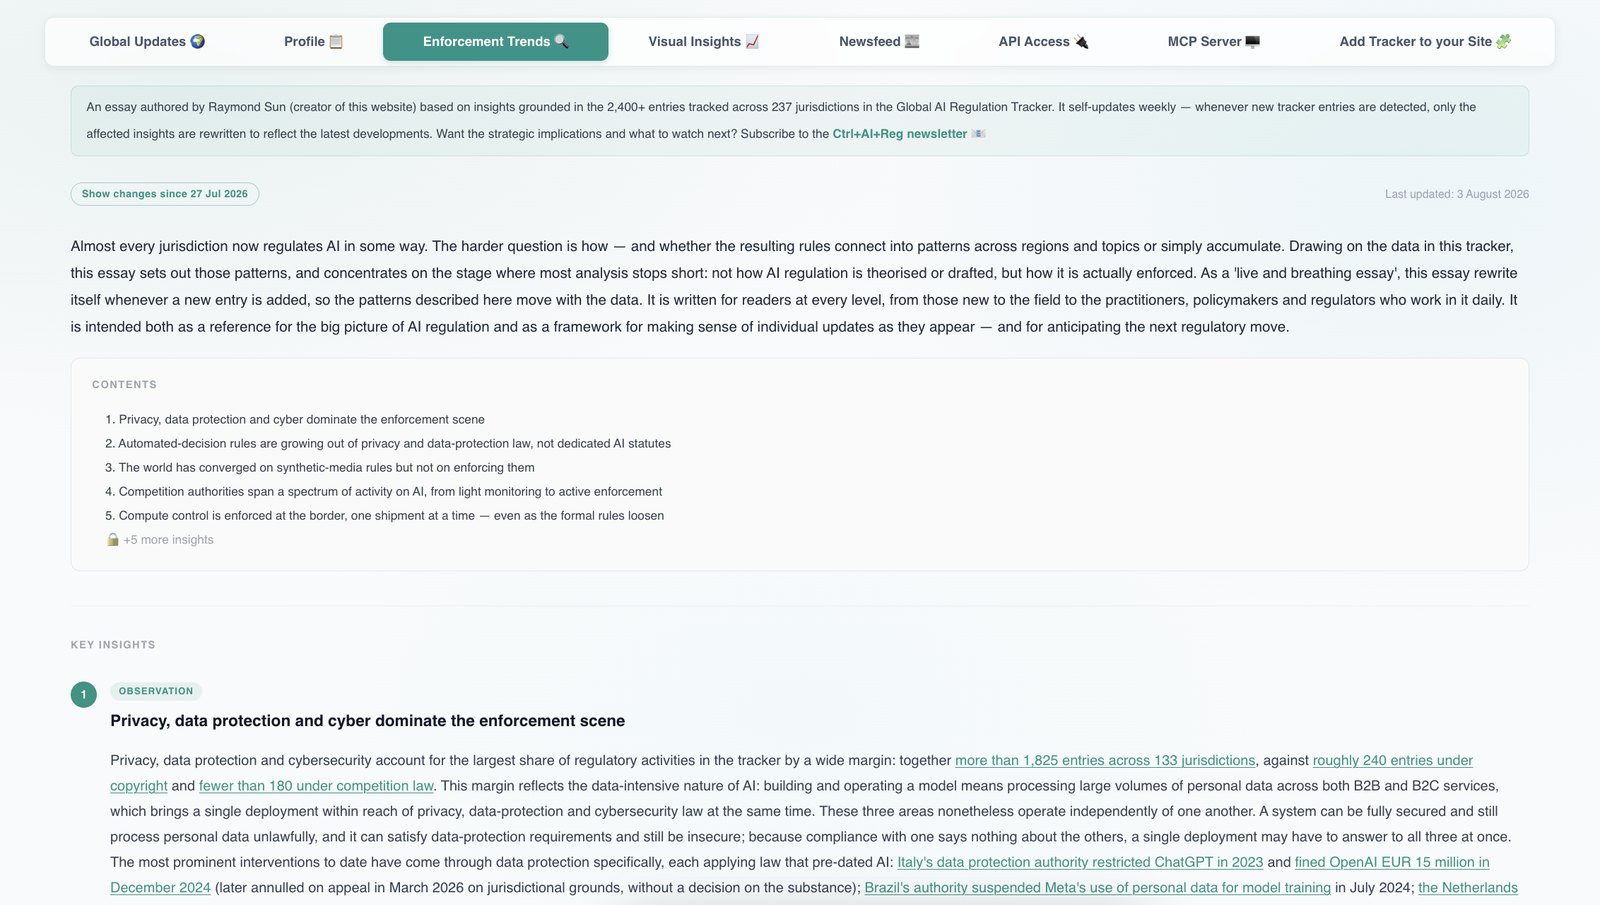
The page is rendered from one JSON file in a Cloud Storage bucket. Below is an excerpt of the live file, cut down to a single insight and with the long values elided. Each field in it does one job.
{
  "schema_version": 2,
  "generated_at": "2026-08-02T17:04:49.920Z",

  "insights": [
    {
      "id": "fa_personal_data",
      "type": "observation",
      "heading": "Privacy, data protection and cyber dominate …",
      "body": "<p>Privacy, data protection and cyber account …",
      "examples": [
        { "country_code": "IT",
          "label": "[20 December 2024] Italy's data protection …",
          "href": "https://www.gpdp.it/home/docweb/…" }
      ],
      "route": {
        "scope": "thematic",
        "categories": ["Data Privacy & Protection",
                       "Cybersecurity", "…"],
        "jurisdictions": ["IT", "EU", "BR", "CN", "AU", "…"]
      },
      "provenance": {
        "input_hash":   "ead4a8d2fe7e1267592b3efa268d84fb",
        "generated_at": "2026-08-02T17:01:51.352Z",
        "model":        "gpt-5.5"
      }
    }
  ],

  "dataset": {
    "entry_count": 4529,
    "jurisdiction_count": 238,
    "entry_hashes": ["a3a49e3706d3c698dcb8d5af60e255cd", "…"]
  },

  "backlog": {
    "unrouted_hashes": ["6a40c1bdea47c5cd19c088c946f17d34", "…"],
    "by_category": {
      "Civil Rights & Liberties": [
        "f9553ab247ab0ba5aaccf3f03a12f926", "…"]
    }
  }
}
id (Unique ID): A fixed identifier so other systems and
maps can target an insight directly. This allows you to reorder the essay without breaking
code.type (Insight Type): Shows whether the point is an
observation (what current data says) or a prediction (where things are heading), as
predictions update under different rules.heading & body (The Text): The rendered
title and text readers actually see. They are generated outputs, so no system logic depends
on them.examples (Sources): The source evidence. Each contains a
country code, summary, and direct link so citations resolve automatically without manual
checks.route (The Subject): Maps categories to insights so the
code automatically routes incoming data to the correct place.provenance.input_hash (Input Fingerprint): The content
hash of the source data behind the insight, as defined in 2.2. A changed source produces
a changed fingerprint.provenance.generated_at (Check Date): The timestamp
showing when this specific insight was last checked against its sources.provenance.model (AI Model): Records which AI model wrote
the insight for auditability.dataset.entry_hashes (Intake Ledger): The ledger from
2.2, the master list of processed entry hashes that stops the same entry being taken in
twice.backlog (Unassigned Items): A holding area for entries
that didn't match an existing insight. A growing category here alerts you that a new
insight needs to be created.Listing 2. An excerpt of the live essay file, one insight of ten, with long values elided.
The whole update process runs automatically inside a single program hosted in the cloud,
called updatebigpicture. Think of it like a temporary digital assistant that wakes
up when triggered, runs the routine, and shuts down the moment it finishes. Here is how one run
works, step by step.
essay.pending.json. The live document, essay.json, stays completely
unchanged until you review and approve the updates in the admin dashboard.
Over two months the service handled a few dozen requests and was idle between them. Each run finishes in minutes.
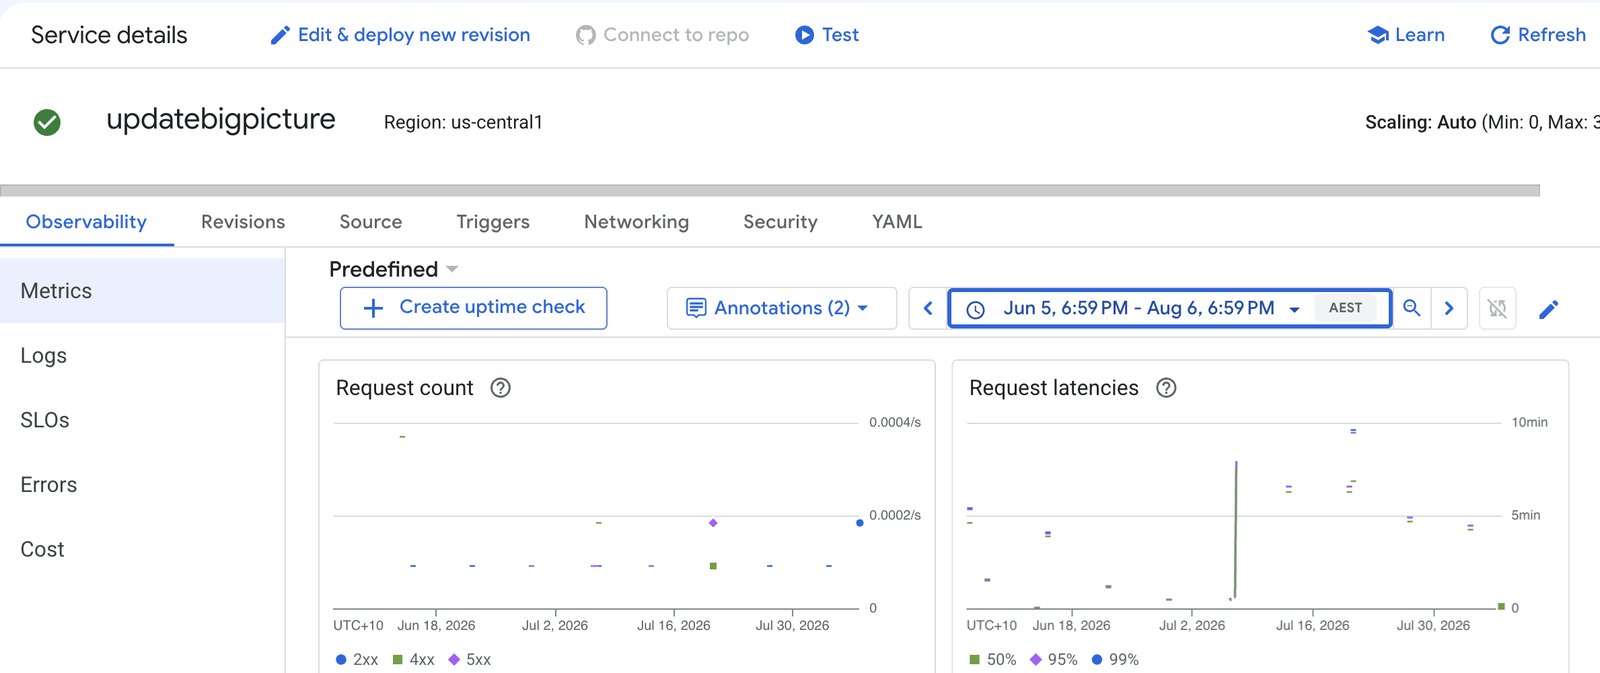
updatebigpicture service, with two months
of request count and latency. The service is idle between runs and is invoked by the
scheduler in 3.4.
The scheduler is Cloud Scheduler, a managed cron service. You give it a schedule, a target to call and a way to authenticate, and it makes that call on time whether or not anything else is running.
The job is bigpicture-weekly. It runs on 0 3 * * 1 in
Australia/Melbourne, which is three in the morning every Monday, and it calls the service in
3.3 with a signed token the service checks before it does anything.
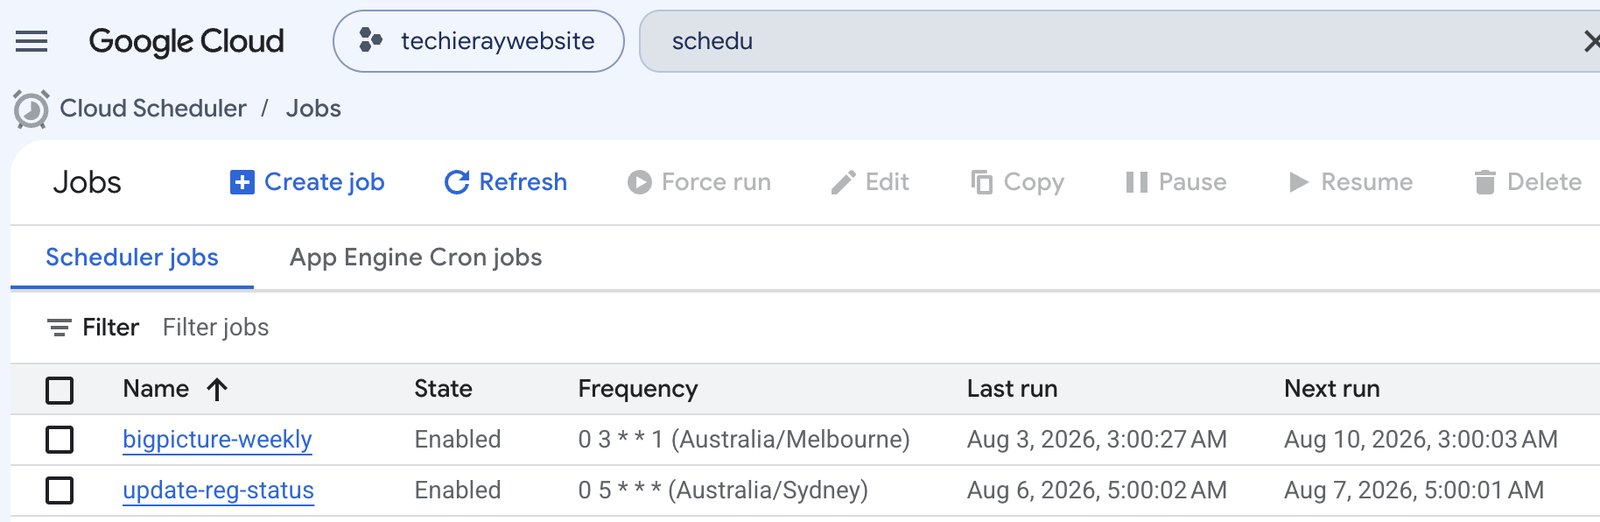
bigpicture-weekly, enabled, weekly, with its
last run and next run. The second job in the list is unrelated to the essay.
The approval mechanism is a private web based control panel, and the only tool allowed to edit
and publish the final essay, essay.json.
When you open the dashboard, it compares the current draft, essay.pending.json,
against the live essay, essay.json, word by word. It then shows the essay with
proposed additions and removals highlighted in place. Every highlighted change is an
independent decision, and every one defaults to accept.
For every change you have three options.
essay.json. It saves a permanent timestamped log of the draft and your decisions
for the record, then clears out the pending draft. Saving the live file also updates the show
what changed feature on the public page automatically.
Safety check. To prevent accidental overwrites, the system locks every review to a fingerprint of the draft you opened. If a background run creates a fresh draft while you are still reviewing an older one, the system blocks the save and prompts you to refresh the page. A newer update is never overwritten by an outdated review.
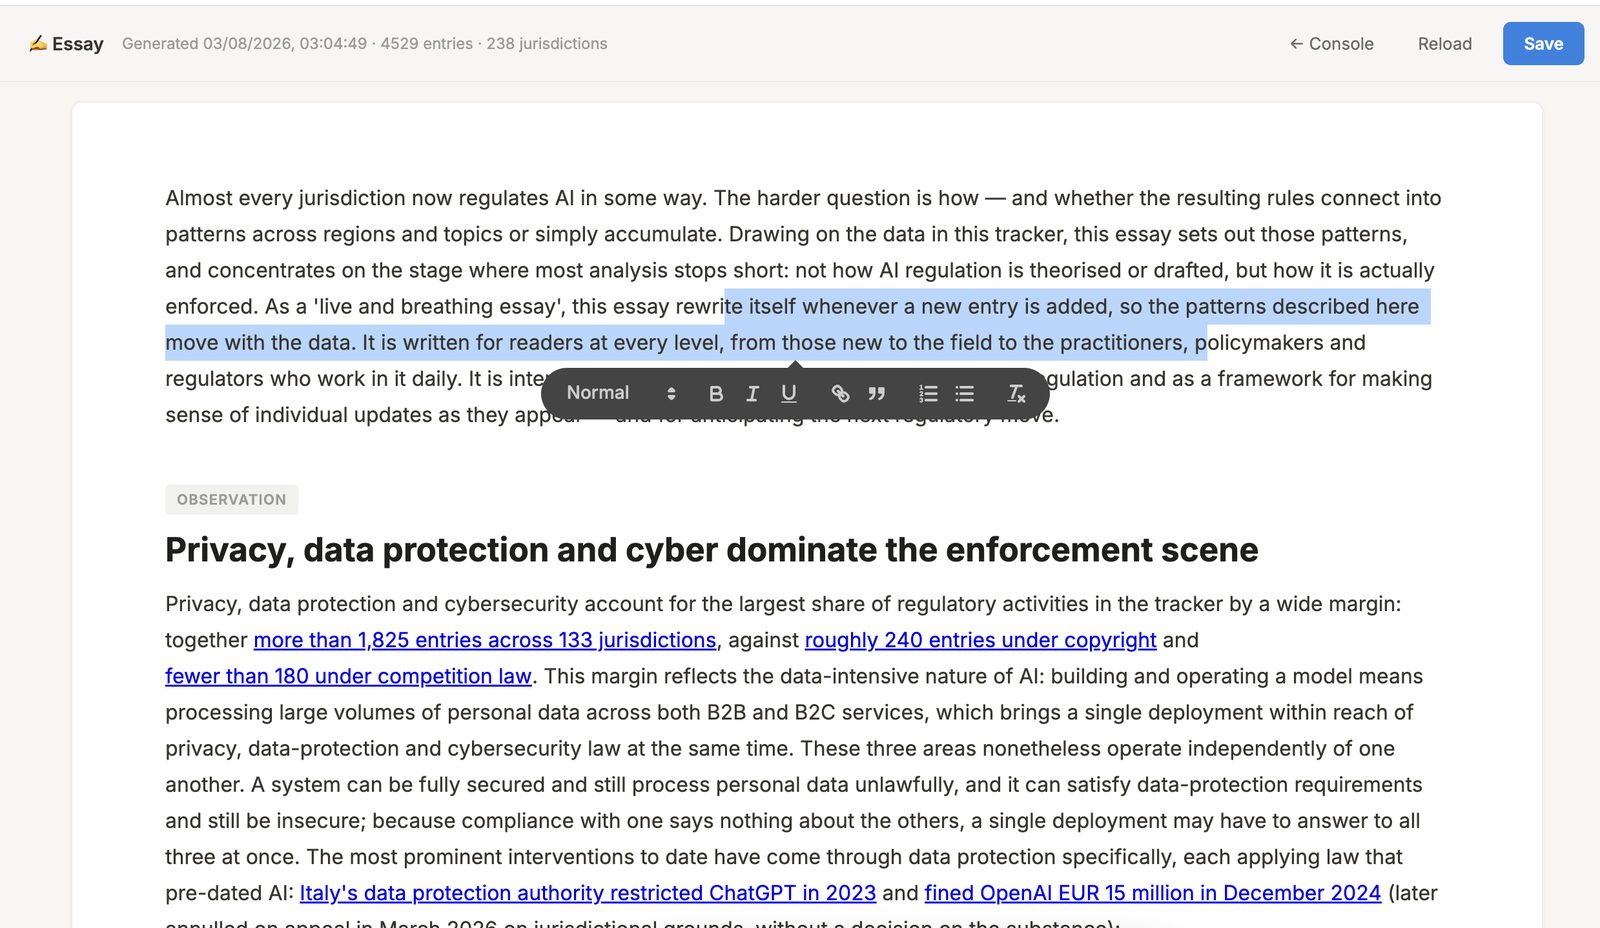
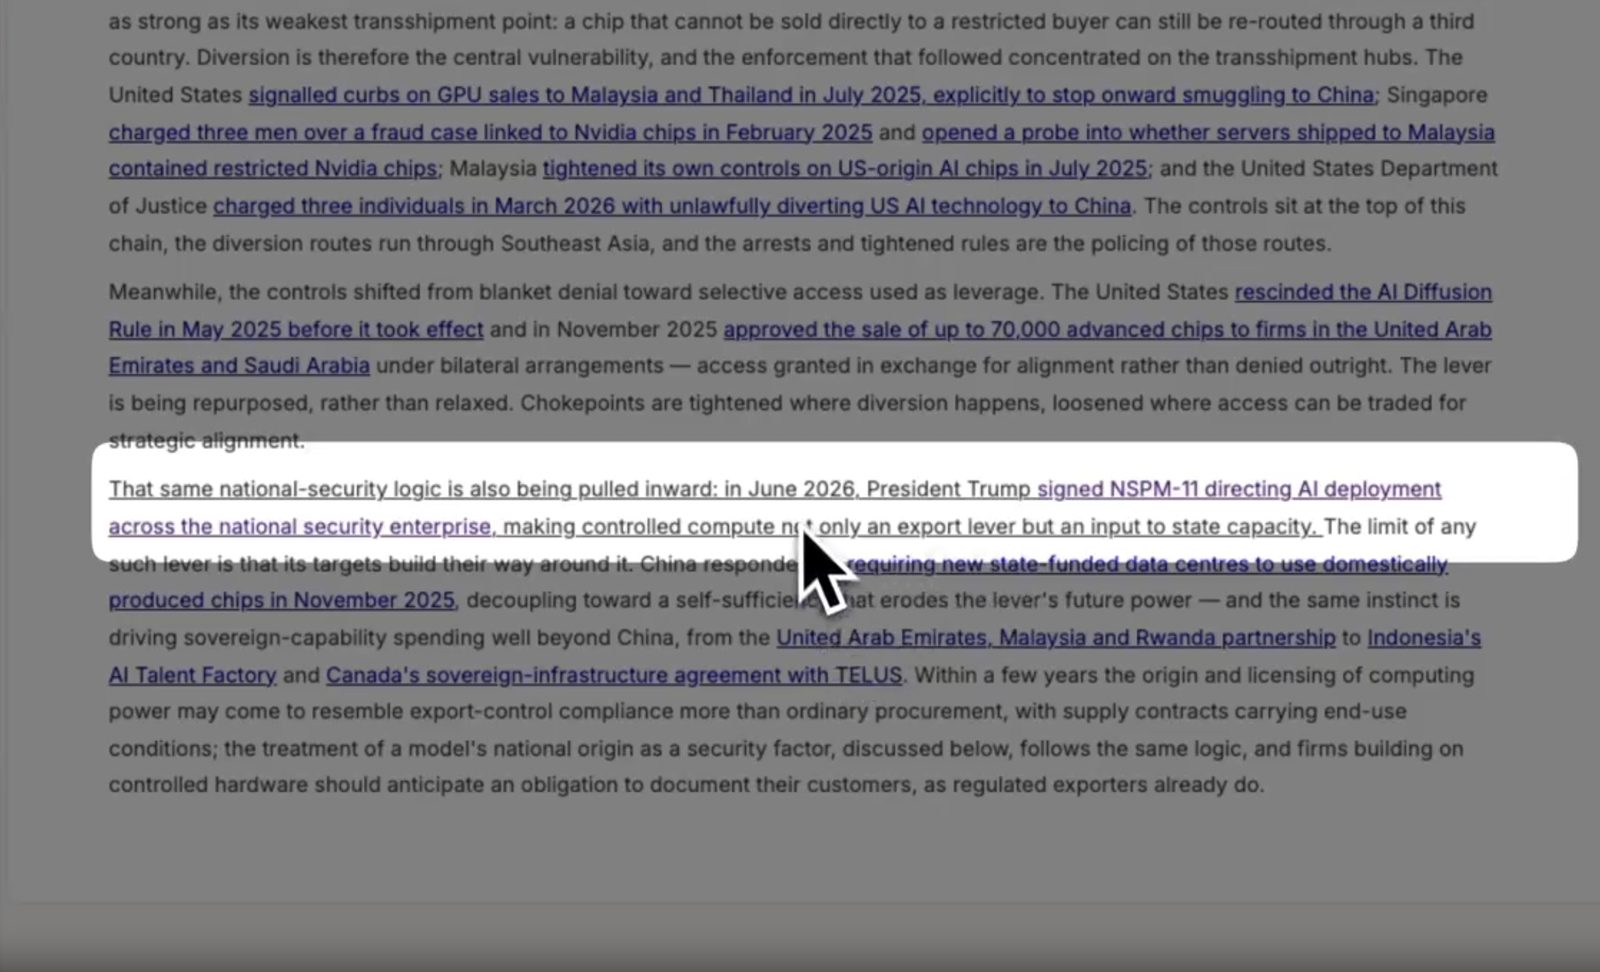
Figure 7 runs all five components together over one week on Google Cloud. Cloud Scheduler triggers the run, Cloud Run executes the algorithm, Cloud Storage holds the mesh and the draft, and Firebase Hosting serves the rebuilt page, so the whole architecture runs as one pipeline. The strip along the top is the same wiring as Figure 1, with the Google Cloud service under each component.
essay.json, completely
untouched because it has no write access. Once you review and accept the change in the
private admin dashboard, the single modified entry updates in storage, and the live public
site rebuilds automatically, showing the updated check date.
Table 1 names the service, feature or format in each stack that does the job of each component.
| Component | Claude | ChatGPT | Google Cloud | AWS | Azure |
|---|---|---|---|---|---|
| 1The frontend essay | An artifact, or a repo published to Pages. | A Canvas, or a repo published to Pages. | Firebase Hosting. | S3 behind CloudFront. | Static Web Apps. |
| 2The backend mesh | JSON files in a Project. | JSON files in a Project. | JSON in Cloud Storage, or Firebase Realtime Database. | JSON in S3, or DynamoDB tables. | JSON in Blob Storage, or Cosmos DB containers. |
| 3The algorithm | A Skill for the method, connectors for the sources, drafts to a repo. | Project instructions for the method, Actions for the sources, drafts to a repo. | Cloud Run, drafts to a second Cloud Storage file. | Lambda and Bedrock, drafts to a private S3 prefix. | Azure Functions and Azure OpenAI, drafts to a private Blob container. |
| 4The scheduler | Scheduled tasks. | Scheduled tasks. | Cloud Scheduler. | EventBridge. | A timer trigger on the function. |
| 5The approval mechanism | A pull request, which is a held draft, a redline and a decision at once. | A pull request, or the Canvas diff view. | A review console on Cloud Run, writing to Cloud Storage. | A review page on Amplify or API Gateway, writing to S3. | A review page on Static Web Apps, writing to Blob Storage. |
Table 1. The five components across five stacks, checked 6 August 2026. Slide sideways for the rest.
The live and breathing essay solves a problem every publisher of dated writing already has. The content only stays useful while somebody keeps it current, and keeping it current by hand does not scale. Any field with writing that dates on a known schedule, and a dataset behind it that records when, can be built this way. Here is where I would start looking.
The paper is published under CC BY 4.0.
Sun, R. (2026). The Live and Breathing Essay: an architecture for published writing that maintains itself against a live dataset. Version 1.0, 15 August 2026. https://www.techieray.com/LiveAndBreathingEssay